Project
- Discipline
- Software
- Timeline
- May 2026Installed, debugged, themed and extended the same day
- Role
- Fork and customizationBug fix, re-theme, auto-rescan, system metadata
- Category
- Tools / observabilityPersonal AI usage analytics & cost monitoring
- Upstream
- phuryn/claude-usageThe open-source project the first version was forked from
- Status
- First version retiredRebuilt as versions 2 to 4; v4 is from June 2026
Tools
- Python 3 (stdlib)
- SQLite
- http.server
- Chart.js
- JSONL parsing
- HTML / CSS
Knowing what I'm actually using
I use Claude Code most days — sometimes for hours. Without observability, I had no idea how many tokens I was burning, which projects were costing the most, or whether my workflow was efficient. So I forked the open-source phuryn/claude-usage dashboard, fixed the bug that left it rendering blank, re-themed it under the FORGE name and set it to rescan every 30 seconds so it updates as I work. That was the first version. Versions 2 to 4 are rebuilds of my own; this page and its screenshots show the first.
Version 4, from June 2026, is one Python file: 1,072 lines, standard library only, with live updates over server-sent events.
The dashboard is Python with zero dependencies — just stdlib (sqlite3, http.server, pathlib) and Chart.js from a CDN. It reads Claude Code's local JSONL transcripts at ~/.claude/projects/, parses them into a SQLite database at ~/.claude/usage.db, then serves an HTML dashboard on localhost:8080 with token usage, cost estimates, model breakdowns, hourly distribution, and session history.
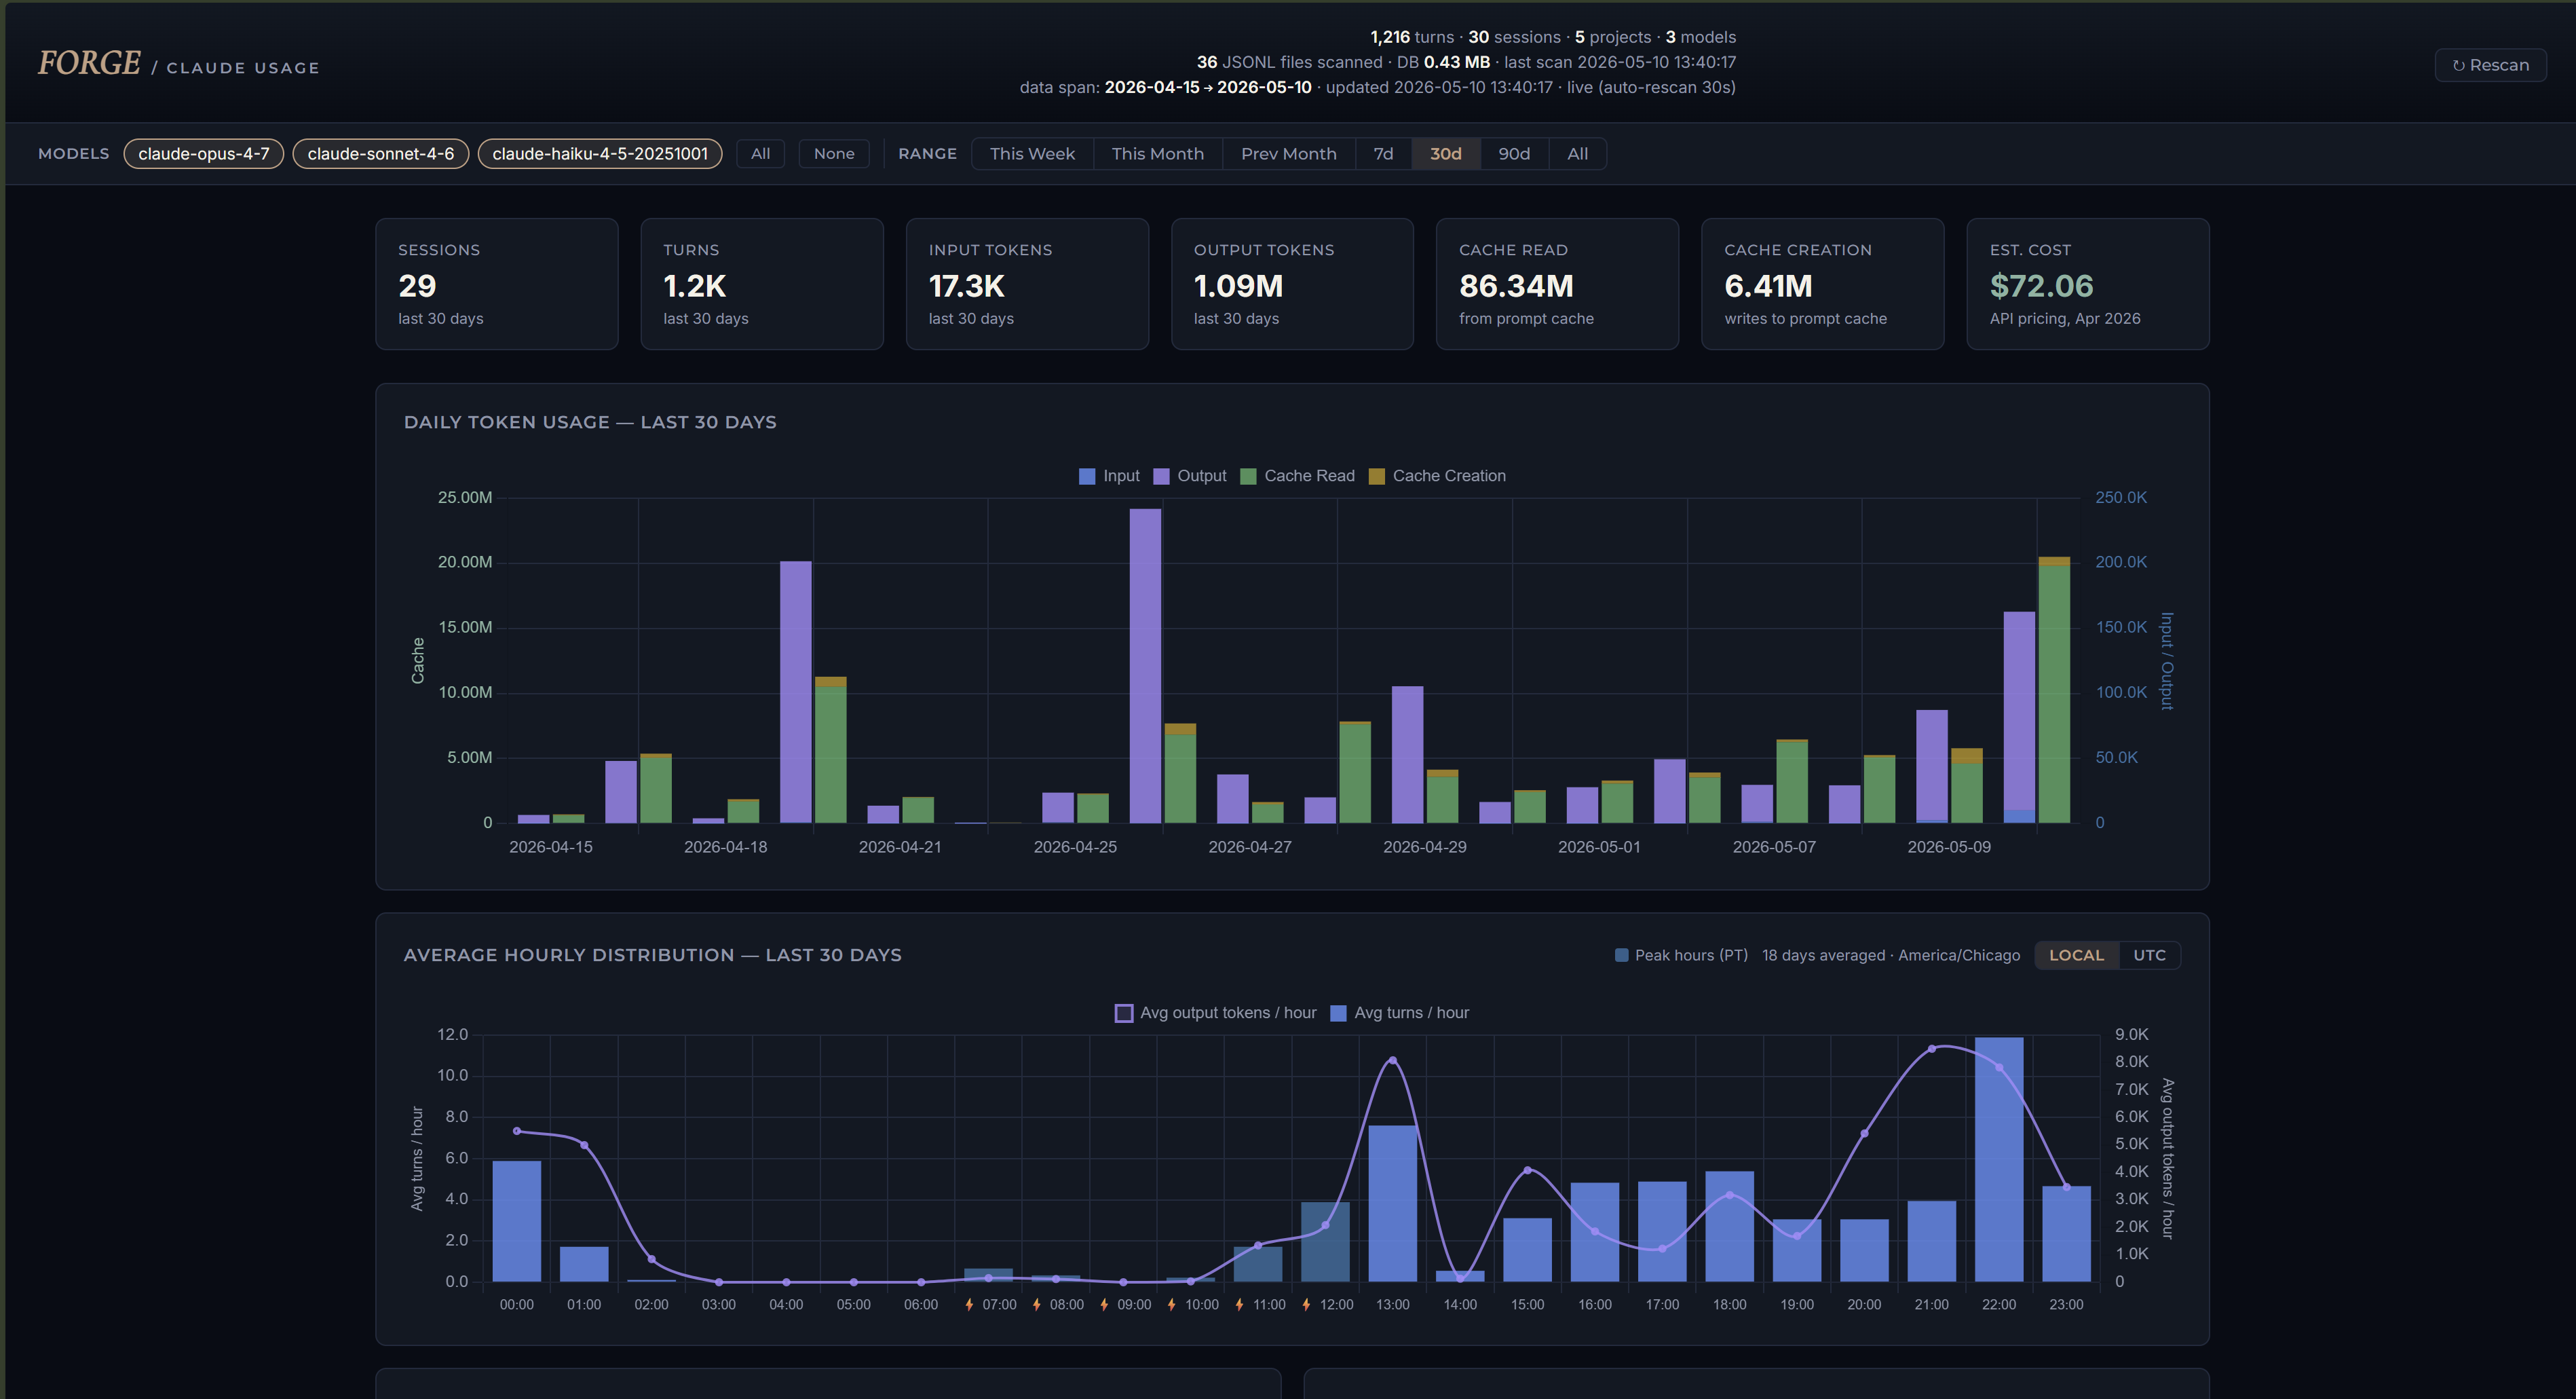
What it showed on 10 May 2026: 1,216 turns across 30 sessions, 1.09M output tokens, 86.34M cache reads, ~$72 in API-equivalent cost over the last 30 days. Top project by token volume: Downloads/Claude_Coding (where most of my dev work happened).
What I contributed
- Bug fix —
dashboard.pyreferenced an undeclared variablecutoffin the hourly filter. The error got swallowed by an outer try/catch inloadData(), killing all renders silently — blank stats row and 4 empty chart cards even though the database had real data. Single-line fix: changed the filter to use the samestart/endvariables as the daily filter. - Dark theme retrofit — rebuilt the color palette: a dark navy background, a gold accent and steel blue.
- Header rebrand — "Claude Code Usage Dashboard" → FORGE / Claude Usage in the header strip, aligned with the FORGE brand.
- Auto-rescan — the 30-second auto-refresh rescans the logs, then loads data, so new Claude session turns appear within about 30 seconds.
- System metadata — the header meta strip shows the database size, last scan time, total turns and sessions, data span, unique projects, JSONL file count and model count.
The full data flow is: Claude Code writes JSONL to ~/.claude/projects/ on every session (always, regardless of whether the dashboard is running). The scanner parses JSONL into a SQLite database. The dashboard reads from SQLite, not from JSONL. Cowork sessions aren't captured because they're server-side and don't write local logs.
One nuance worth noting: the cost estimates use Anthropic's API pricing as of April 2026. Pro and Max subscriptions are flat-fee, so the dollar figure represents "what the API would cost" rather than actual spend. Useful for understanding usage patterns, not for billing. I treat it as a relative metric — am I burning more this week than last? Which project is the heaviest?
First version — screenshots
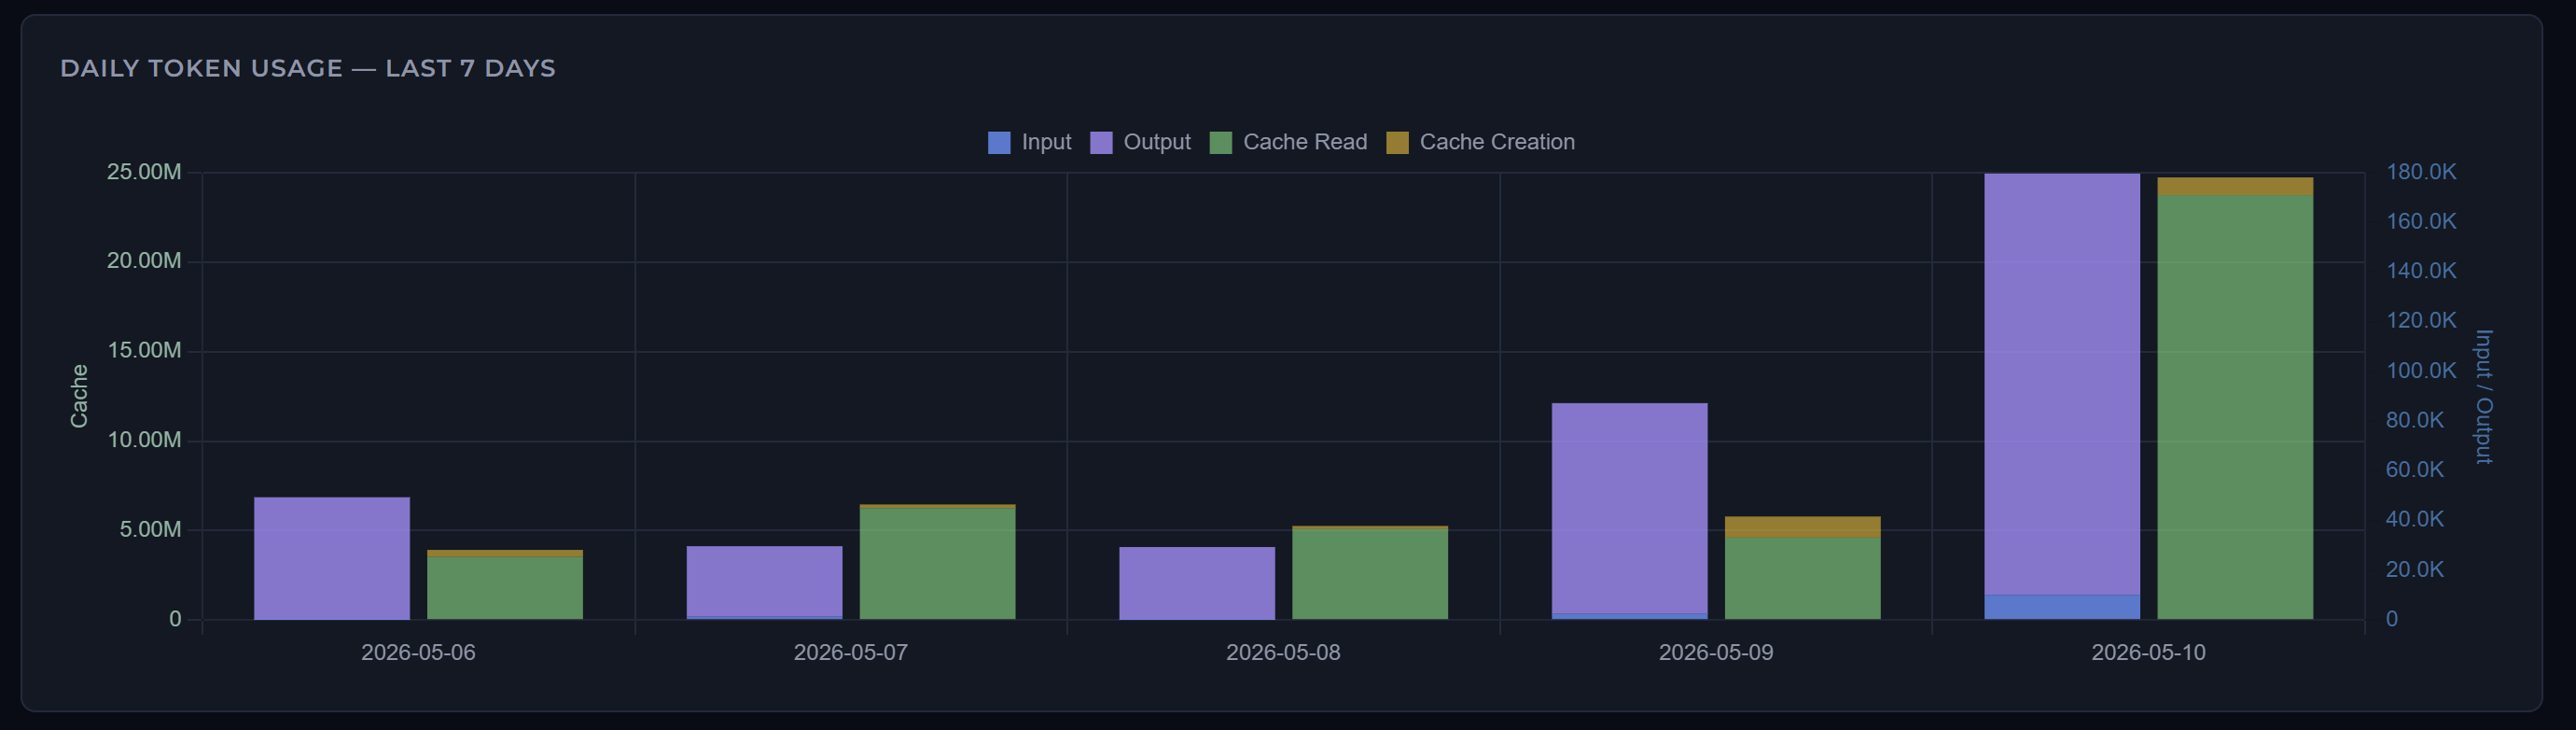
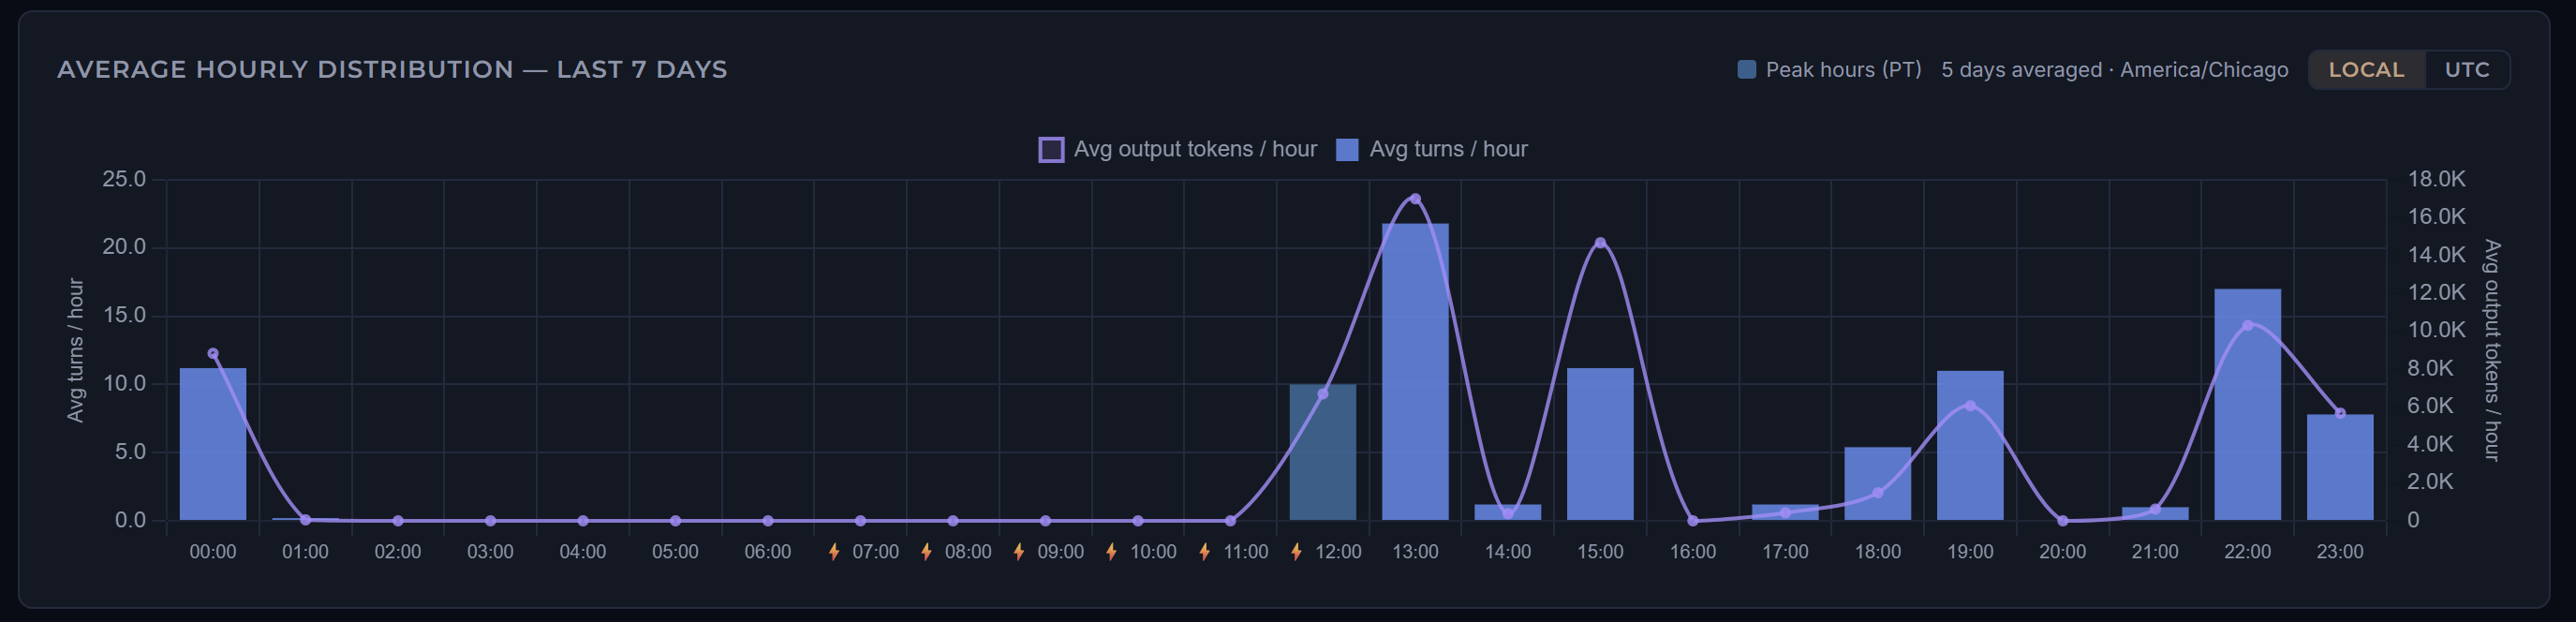
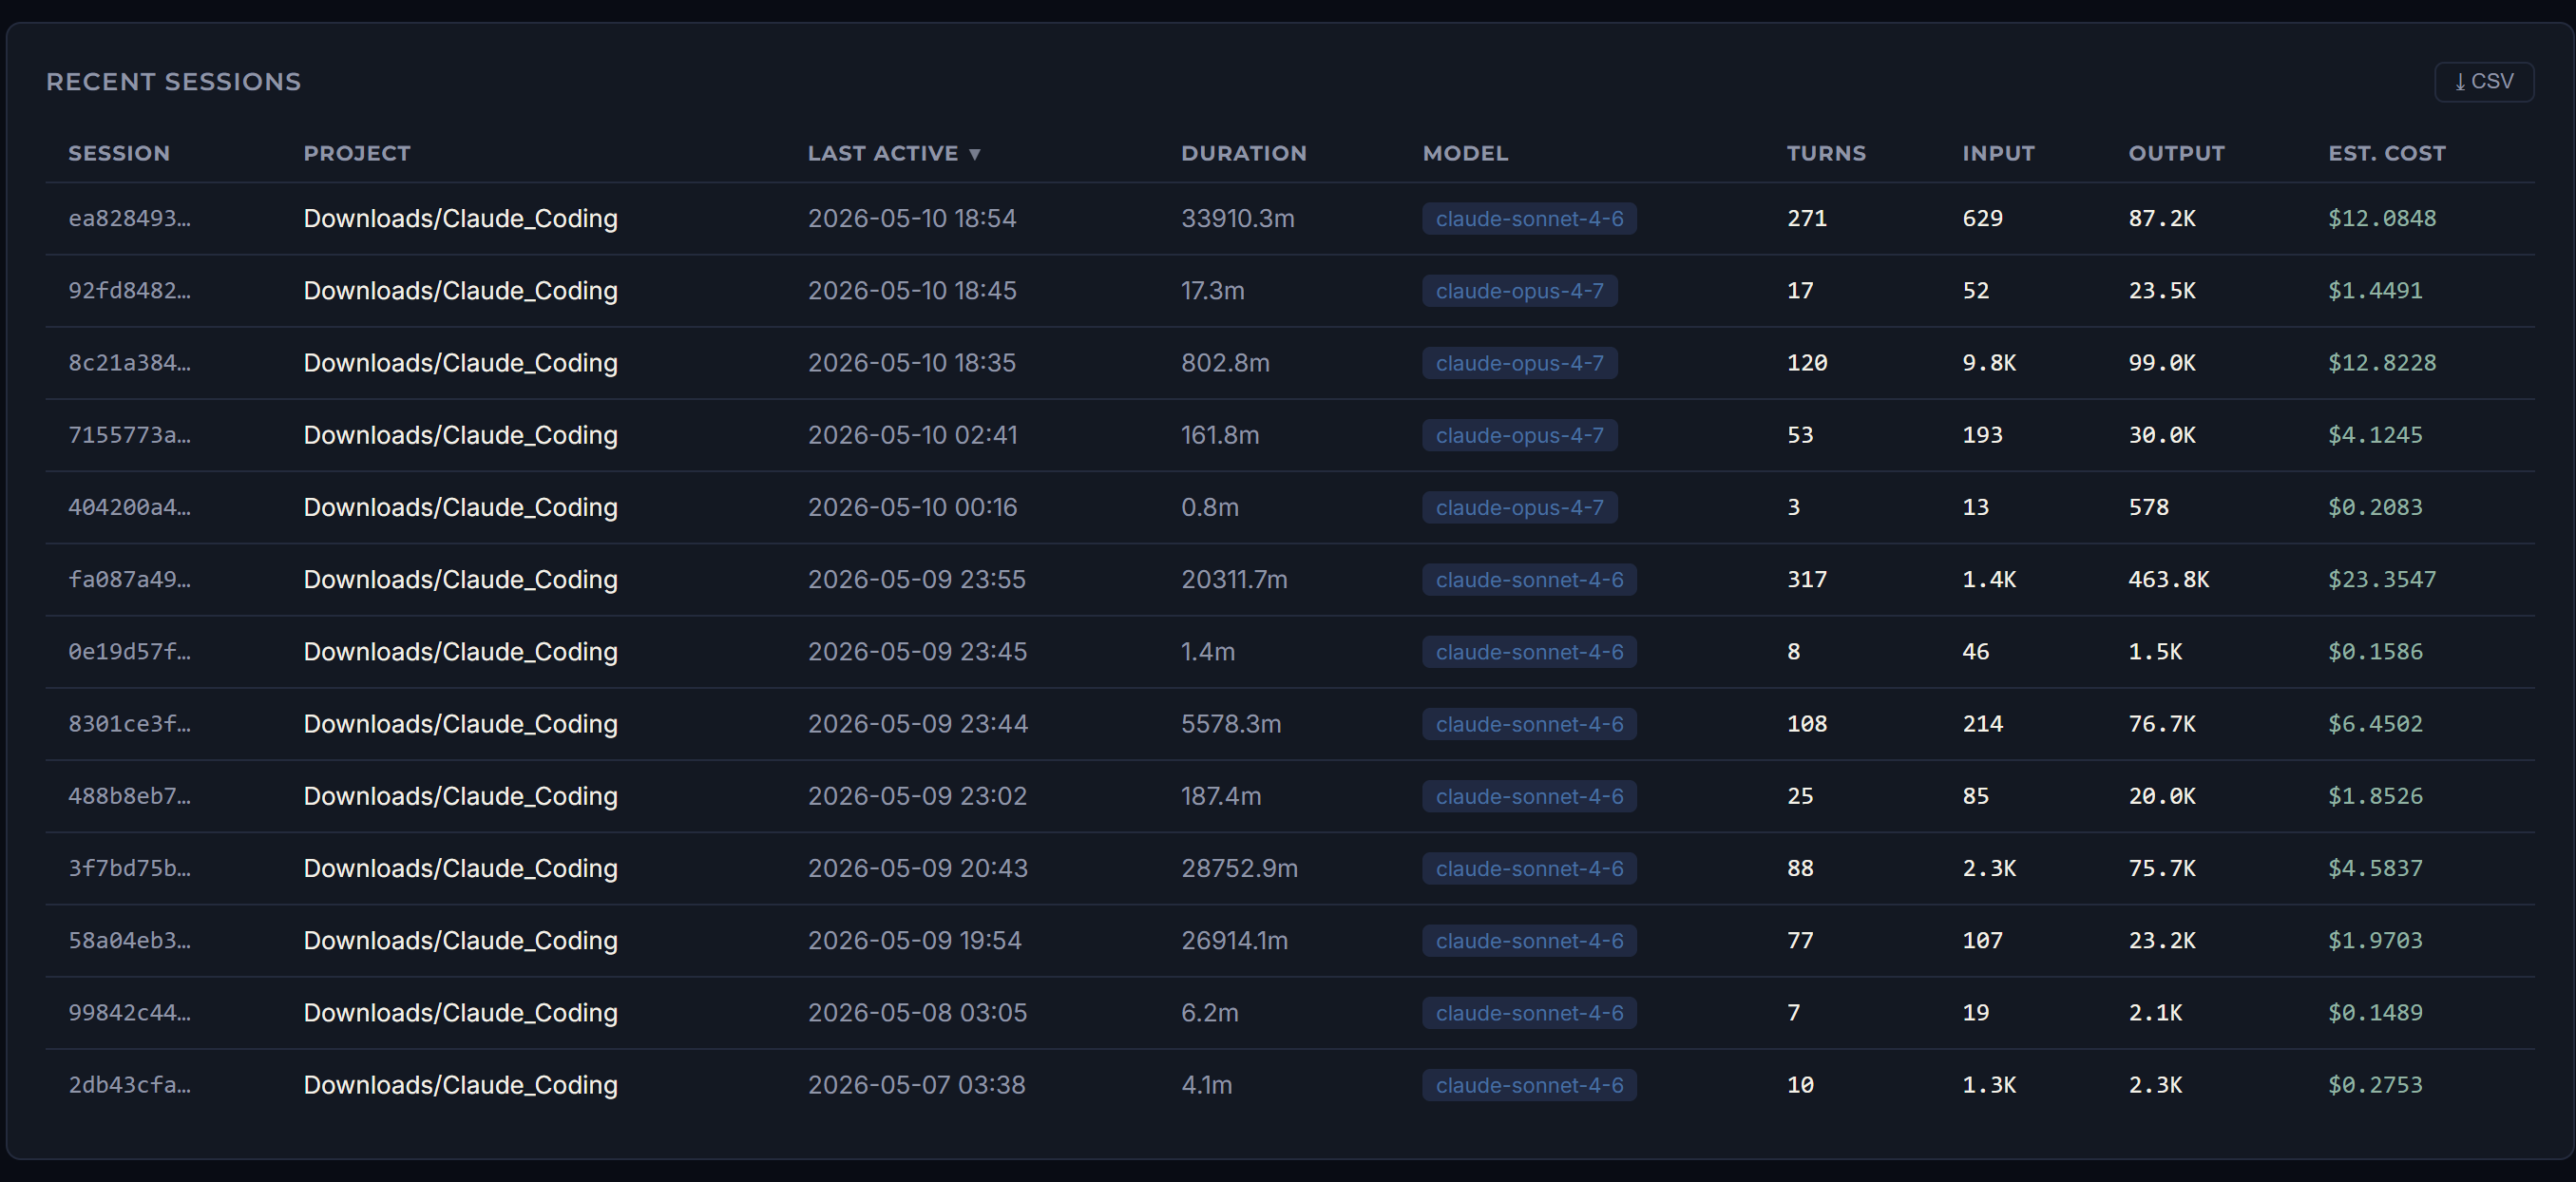
Screenshots from the first version running on localhost:8080 on 10 May 2026 — dark theme retrofit, auto-rescan every 30 seconds, reading from ~/.claude/projects/*.jsonl.
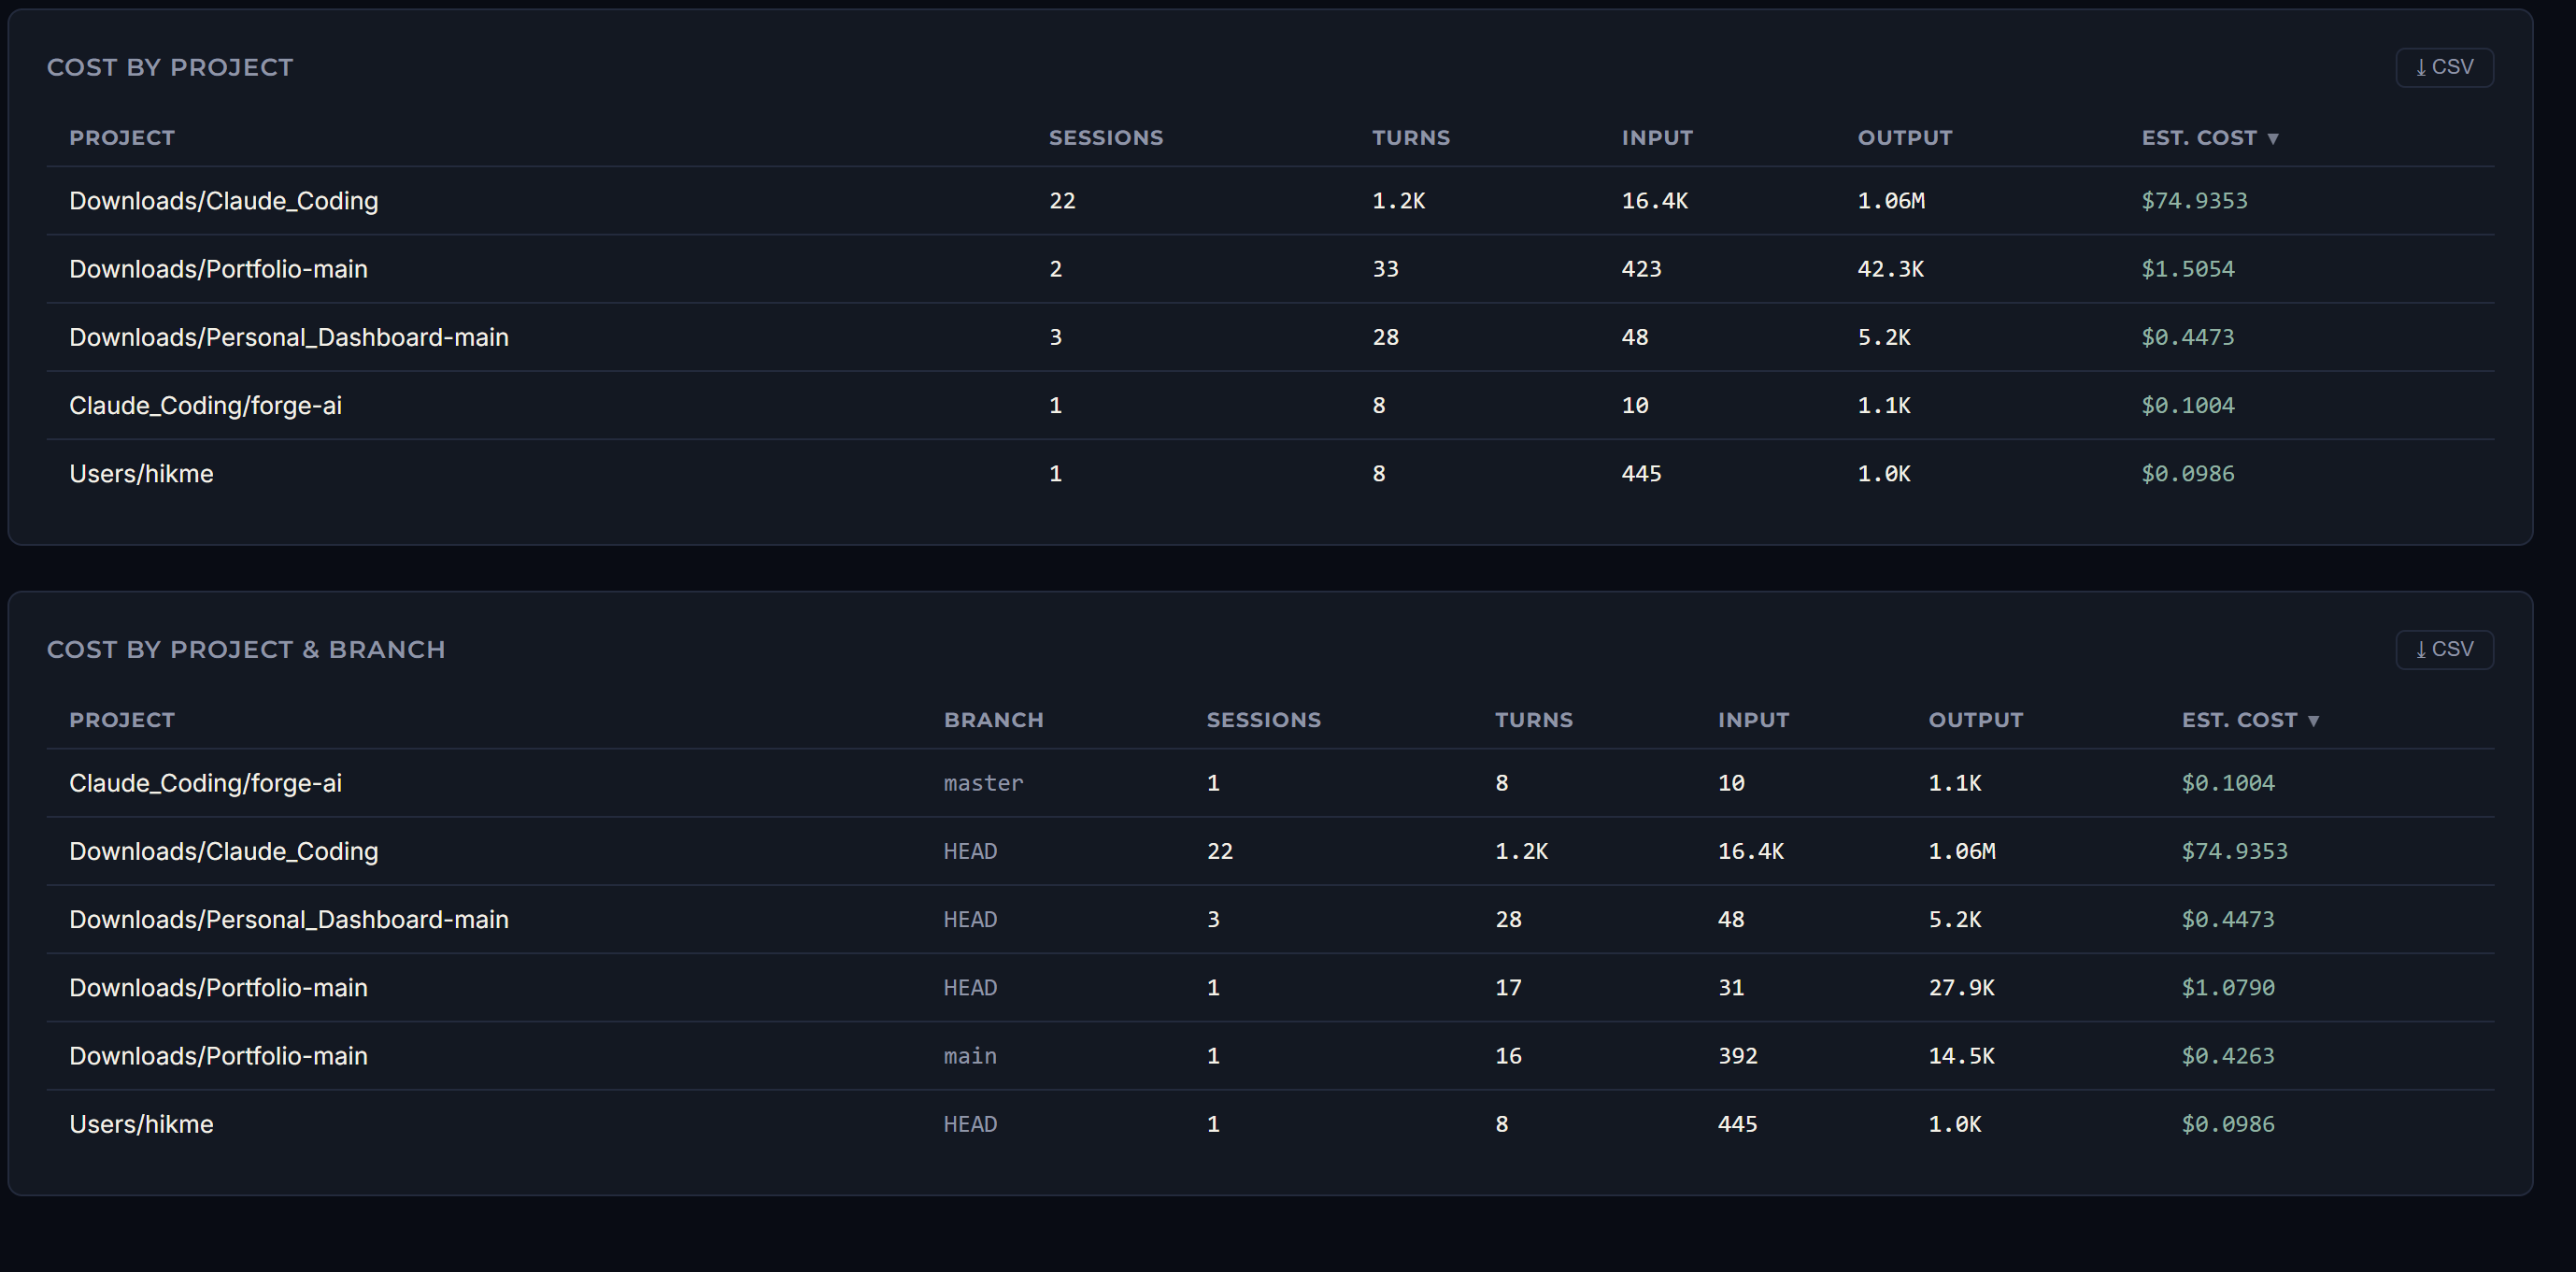
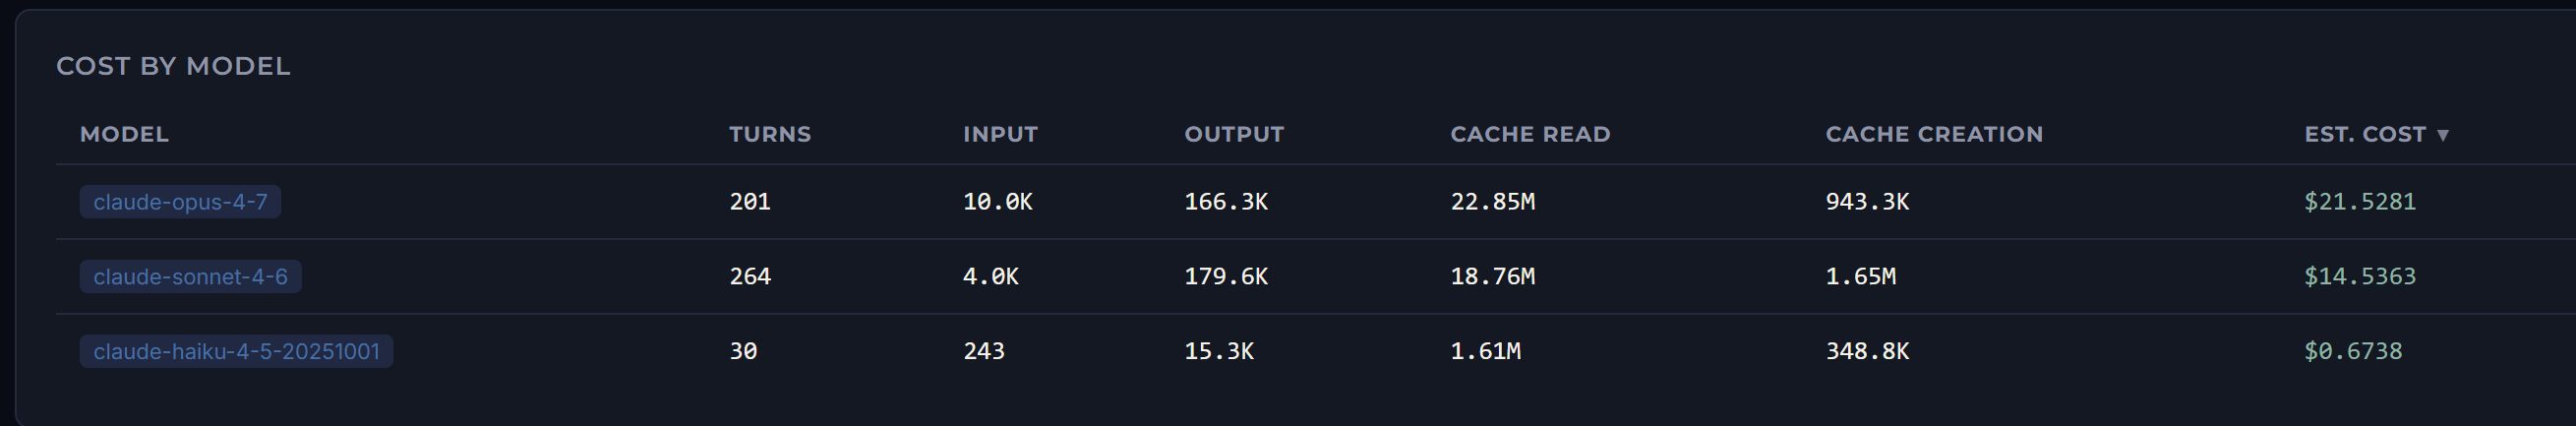
First version, May 2026 · rebuilt as versions 2 to 4 since